AI QA Chatbot & Scorecard Management Platform for Call Center & BPO
We built an AI Call Center QA Chatbot and Scorecard Management Platform to give BPO and contact-center quality teams one structured framework for automated and human evaluation.
The AI QA Chatbot analyzes transcribed customer conversations using configurable AI prompts and keyword rules. Quality teams can evaluate areas such as empathy, professionalism, active listening, greeting quality, customer verification, and objection handling.
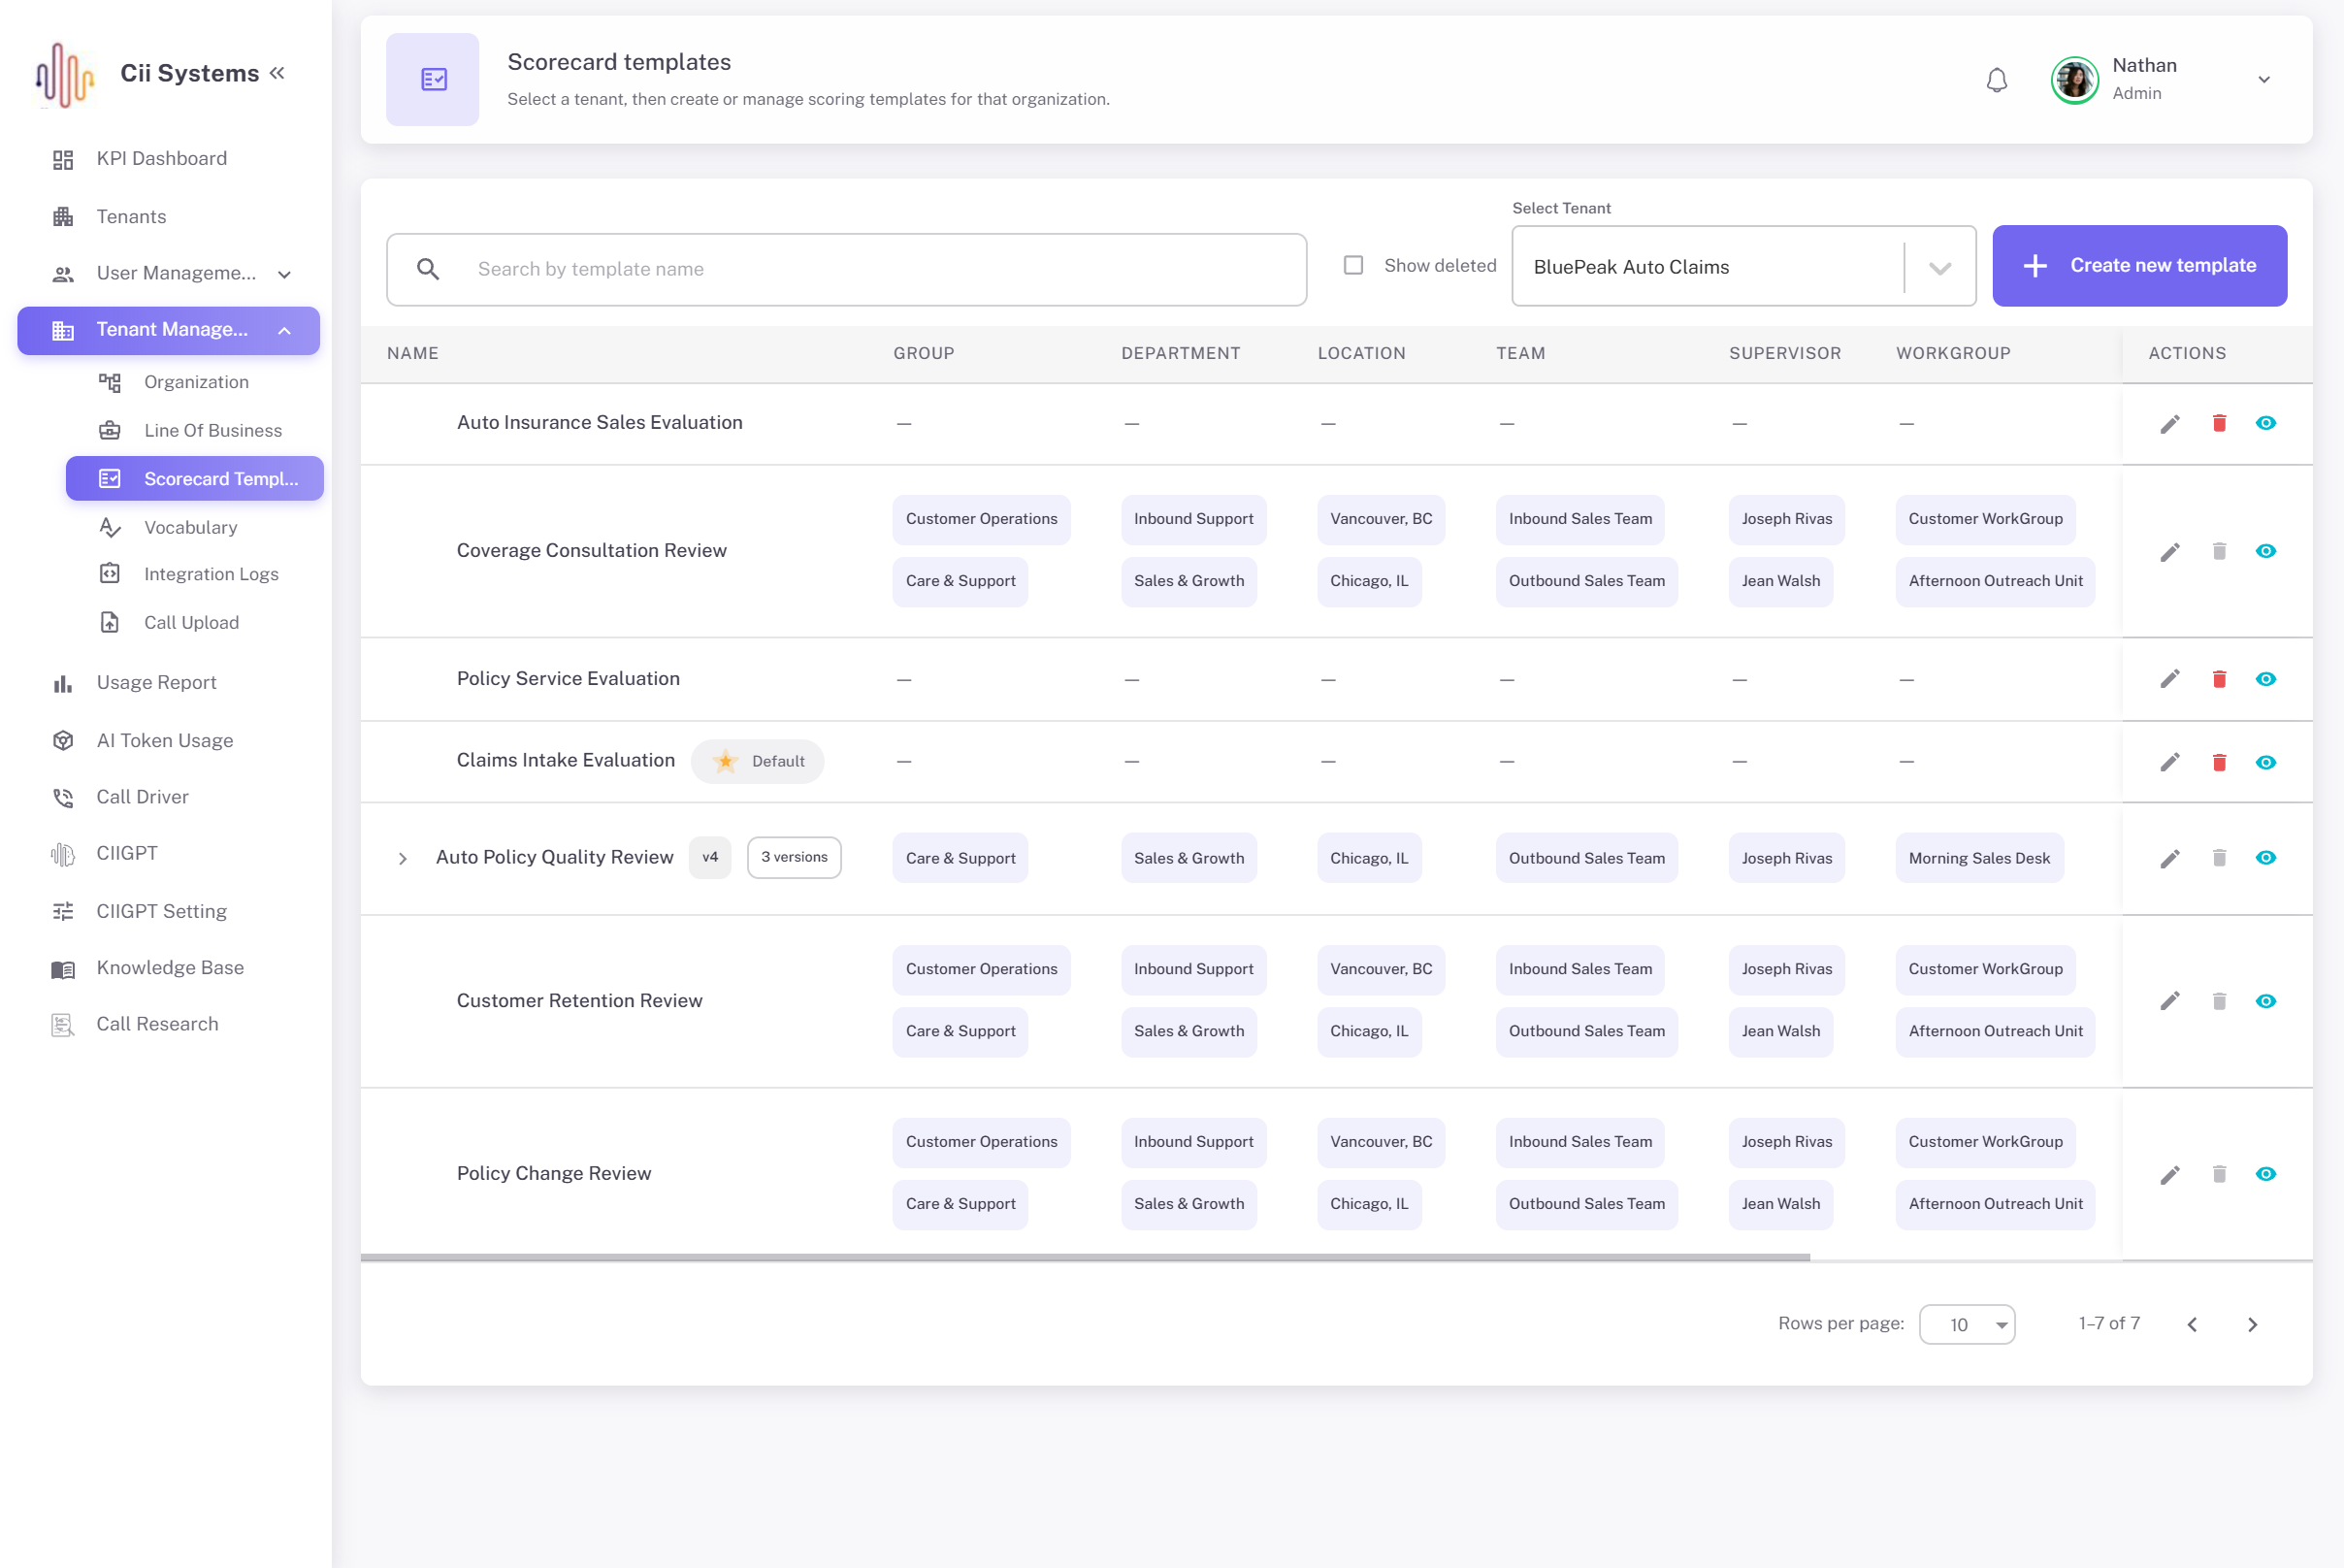
Administrators remain in control of Categories, Subcategories, Definitions, keywords, AI prompts, scoring points, weights, organization assignments, effective dates, and scorecard versions.
Gemini and Vertex AI handle contextual evaluation where simple keyword checks are not enough. Human reviewers use the same scorecard structure, helping AI-based QA and manual review stay aligned.

6 Months
USA
What Is an AI Call Center QA Chatbot & Scorecard Platform?
An AI Call Center QA Chatbot helps contact-center quality teams evaluate transcribed customer conversations using structured scorecards, keyword evidence, and contextual AI analysis.
Keywords work well when the system needs to identify something specific, such as a required greeting or verification phrase. The AI QA Chatbot handles areas where the meaning and tone of the conversation matter more than a particular word.
For example, it can help evaluate whether an agent demonstrated empathy, listened actively, remained professional, or handled an objection appropriately.
Human QA reviewers then work from the same Categories, Definitions, questions, prompts, and scoring rules used by automated QA.
The result is one QA framework for AI-assisted evaluation, manual scoring, review, approval, reopening, rescoring, and historical analysis.
Project Brief
The project centered on a scorecard-management and AI QA workspace within a broader call-center environment.
The goal was not simply to create another scoring form.
The system needed to define exactly how the AI QA Chatbot, automated QA engine, and human reviewers should evaluate customer conversations.
A Quality Leader can configure a scorecard once and use the same structure across:
- AI QA Chatbot
- Automated scoring
- Manual QA
- Review and approval
- Reopening
- Rescoring
- Historical evaluation
Different contact-center operations require different standards.
An inbound sales team may focus on qualification and objection handling. Customer service may place more emphasis on empathy and resolution quality. Collections teams may have their own communication and compliance requirements.
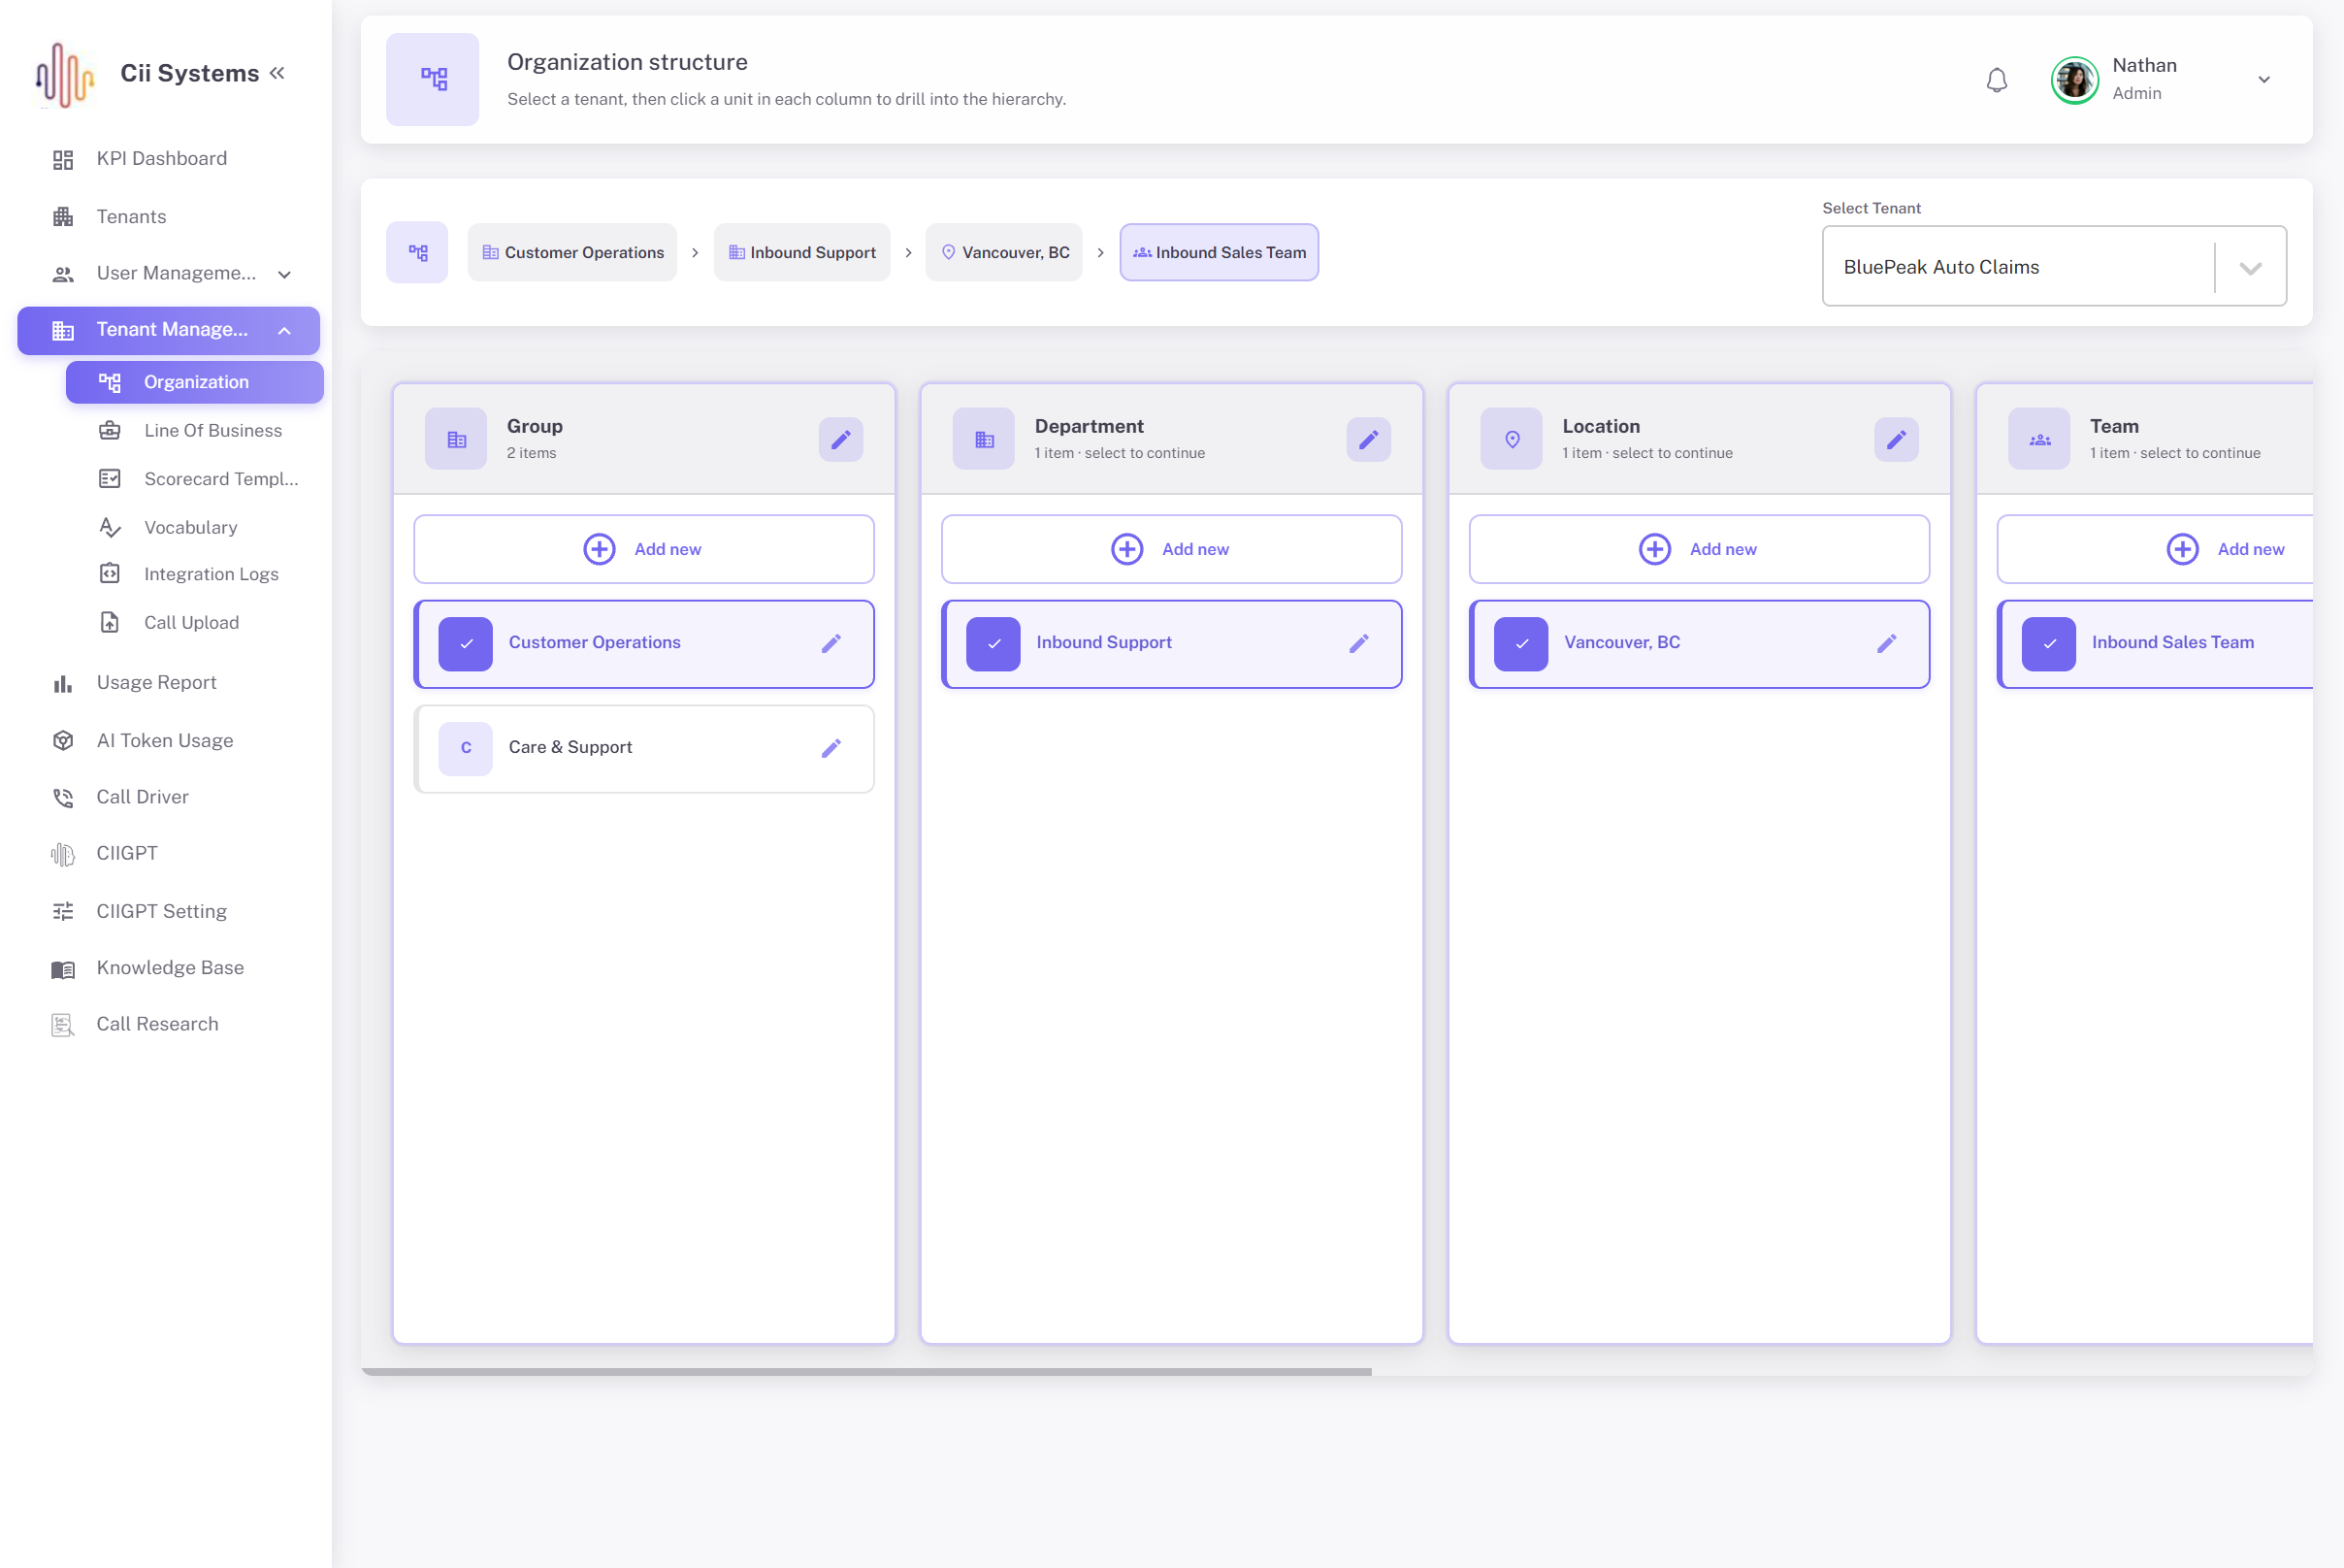
The platform therefore allows quality standards to follow the real organizational structure-from Group and Department through Location, Team, Supervisor, and Workgroup.
Technologies
-

React
-

TypeScript
-

Material UI
-

Redux Toolkit
-

AWS AppSync
-

GraphQL
-

AWS Lambda
-

Amazon Cognito
-

Amazon DynamoDB
-

PostgreSQL
-

Amazon S3
-

Amazon SQS
-

Gemini
-

Vertex AI
Client’s Need
The client needed an AI Call Center QA Chatbot and scorecard system capable of handling detailed quality rules without creating separate standards for AI and human reviewers.
AI-Assisted Call Evaluation
The system needed AI to understand contextual behaviors that simple keyword matching could not reliably assess.Flexible Scorecards
Different contact-center teams required different quality models based on their actual work.Structured Scoring
Complex quality standards needed a clear Category → Subcategory → Definition structure.Keyword Checks
QA teams needed control over phrases, minimum match counts, exact matches, and required keywords.Contextual AI Evaluation
The AI QA Chatbot needed to evaluate areas such as empathy, professionalism, active listening, and objection handling.Visible AI Weighting
Quality leaders needed control over how much keyword evidence and AI evaluation contributed to each score.Shared QA Standards
Automated QA, the AI QA Chatbot, and human reviewers needed to follow the same scoring Definitions.Version History
Changing a scorecard could not erase the rules used to evaluate historical calls.Effective Dates
Quality teams needed control over when new scoring standards became active.Organization-Based Assignment
Scorecards needed to follow the client’s actual Group, Department, Location, Team, Supervisor, and Workgroup hierarchy.Excel Import
Existing large scorecards needed a practical way to enter the platform without rebuilding every rule manually.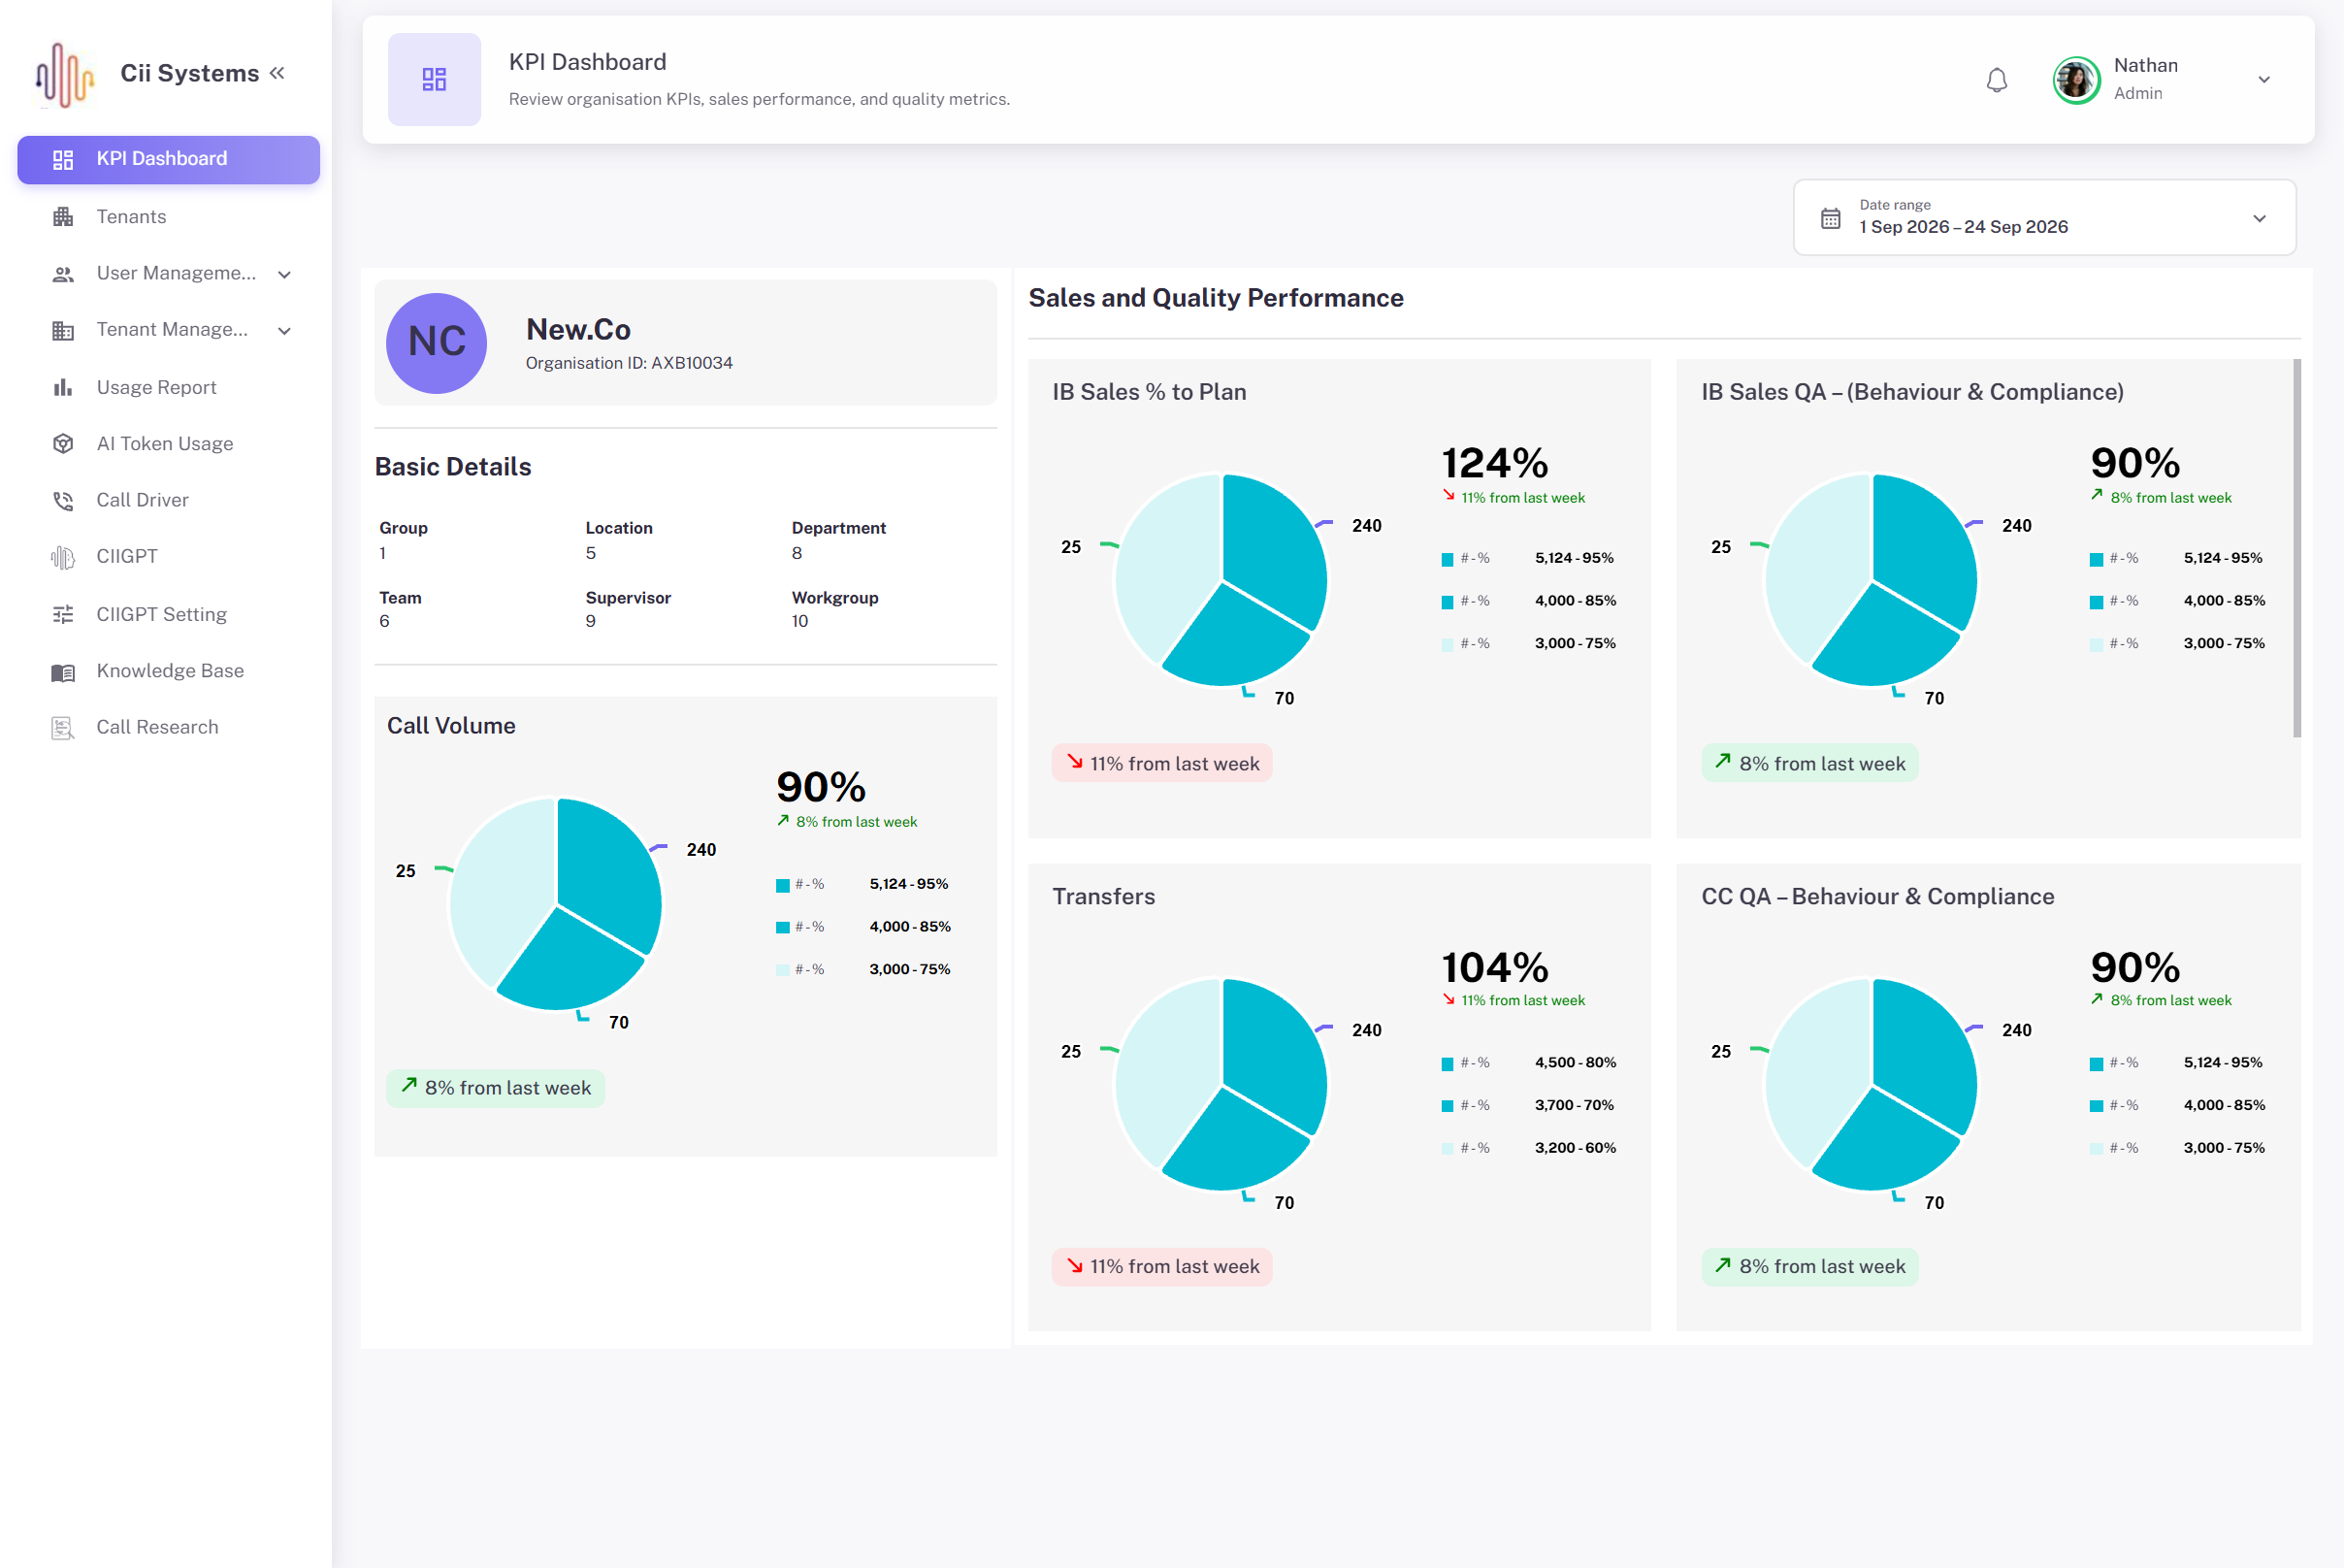
Build an AI QA Chatbot Around Your Contact Center’s Quality Standards
Adding AI to call evaluation is only useful when it follows the quality rules the business actually uses.
The AI QA Chatbot in this platform does not operate with an unrelated scoring model. It works with the same scorecards, Definitions, prompts, points, and organizational assignments used by human QA teams.
That creates a clearer connection between automation and human review while still giving quality leaders control over how each call is evaluated.
Kanhasoft can help businesses build AI-powered applications, AI development solutions, custom BPO and contact-center software, transcript-analysis systems, QA automation platforms, and custom business applications.

Challenges
Different Teams, Different Standards
Sales, collections, service, and other contact-center teams often measure quality differently. One global scorecard would not reflect how those teams actually work.
Keywords Only Tell Part of the Story
A greeting is easy to detect. Whether that greeting sounded professional is a different question. Context-heavy behaviors needed something beyond phrase matching.
Human Scoring Can Vary
Without clear definitions, two experienced reviewers can still score the same interaction differently.
Automated QA and Manual QA Could Drift Apart
If AI uses one set of questions while reviewers use another, the organization ends up comparing two different scoring systems.
Historical Scores Must Still Make Sense
Changing a scorecard in place can create a serious reporting problem. A score from last month should still be traceable to the rules that existed when it was produced.
Organization Structure Was Complex
The scorecard assignment process needed to understand Group, Department, Location, Team, Supervisor, and Workgroup relationships.
Backdated Changes Have Consequences
Applying a scorecard from a date in the past may require existing calls to be reassigned or rescored.
Manual Setup Does Not Scale Well
Re-entering a large scorecard from Excel is slow and introduces another opportunity for mistakes.
AI Needed to Be Explainable
Quality leaders needed to know how much of a result came from a keyword match and how much came from AI judgment.
These requirements meant the project needed much more than an AI prompt attached to a transcript. The real work was in making AI evaluation controlled, repeatable, versioned, and understandable.
Solutions
AI QA Chatbot
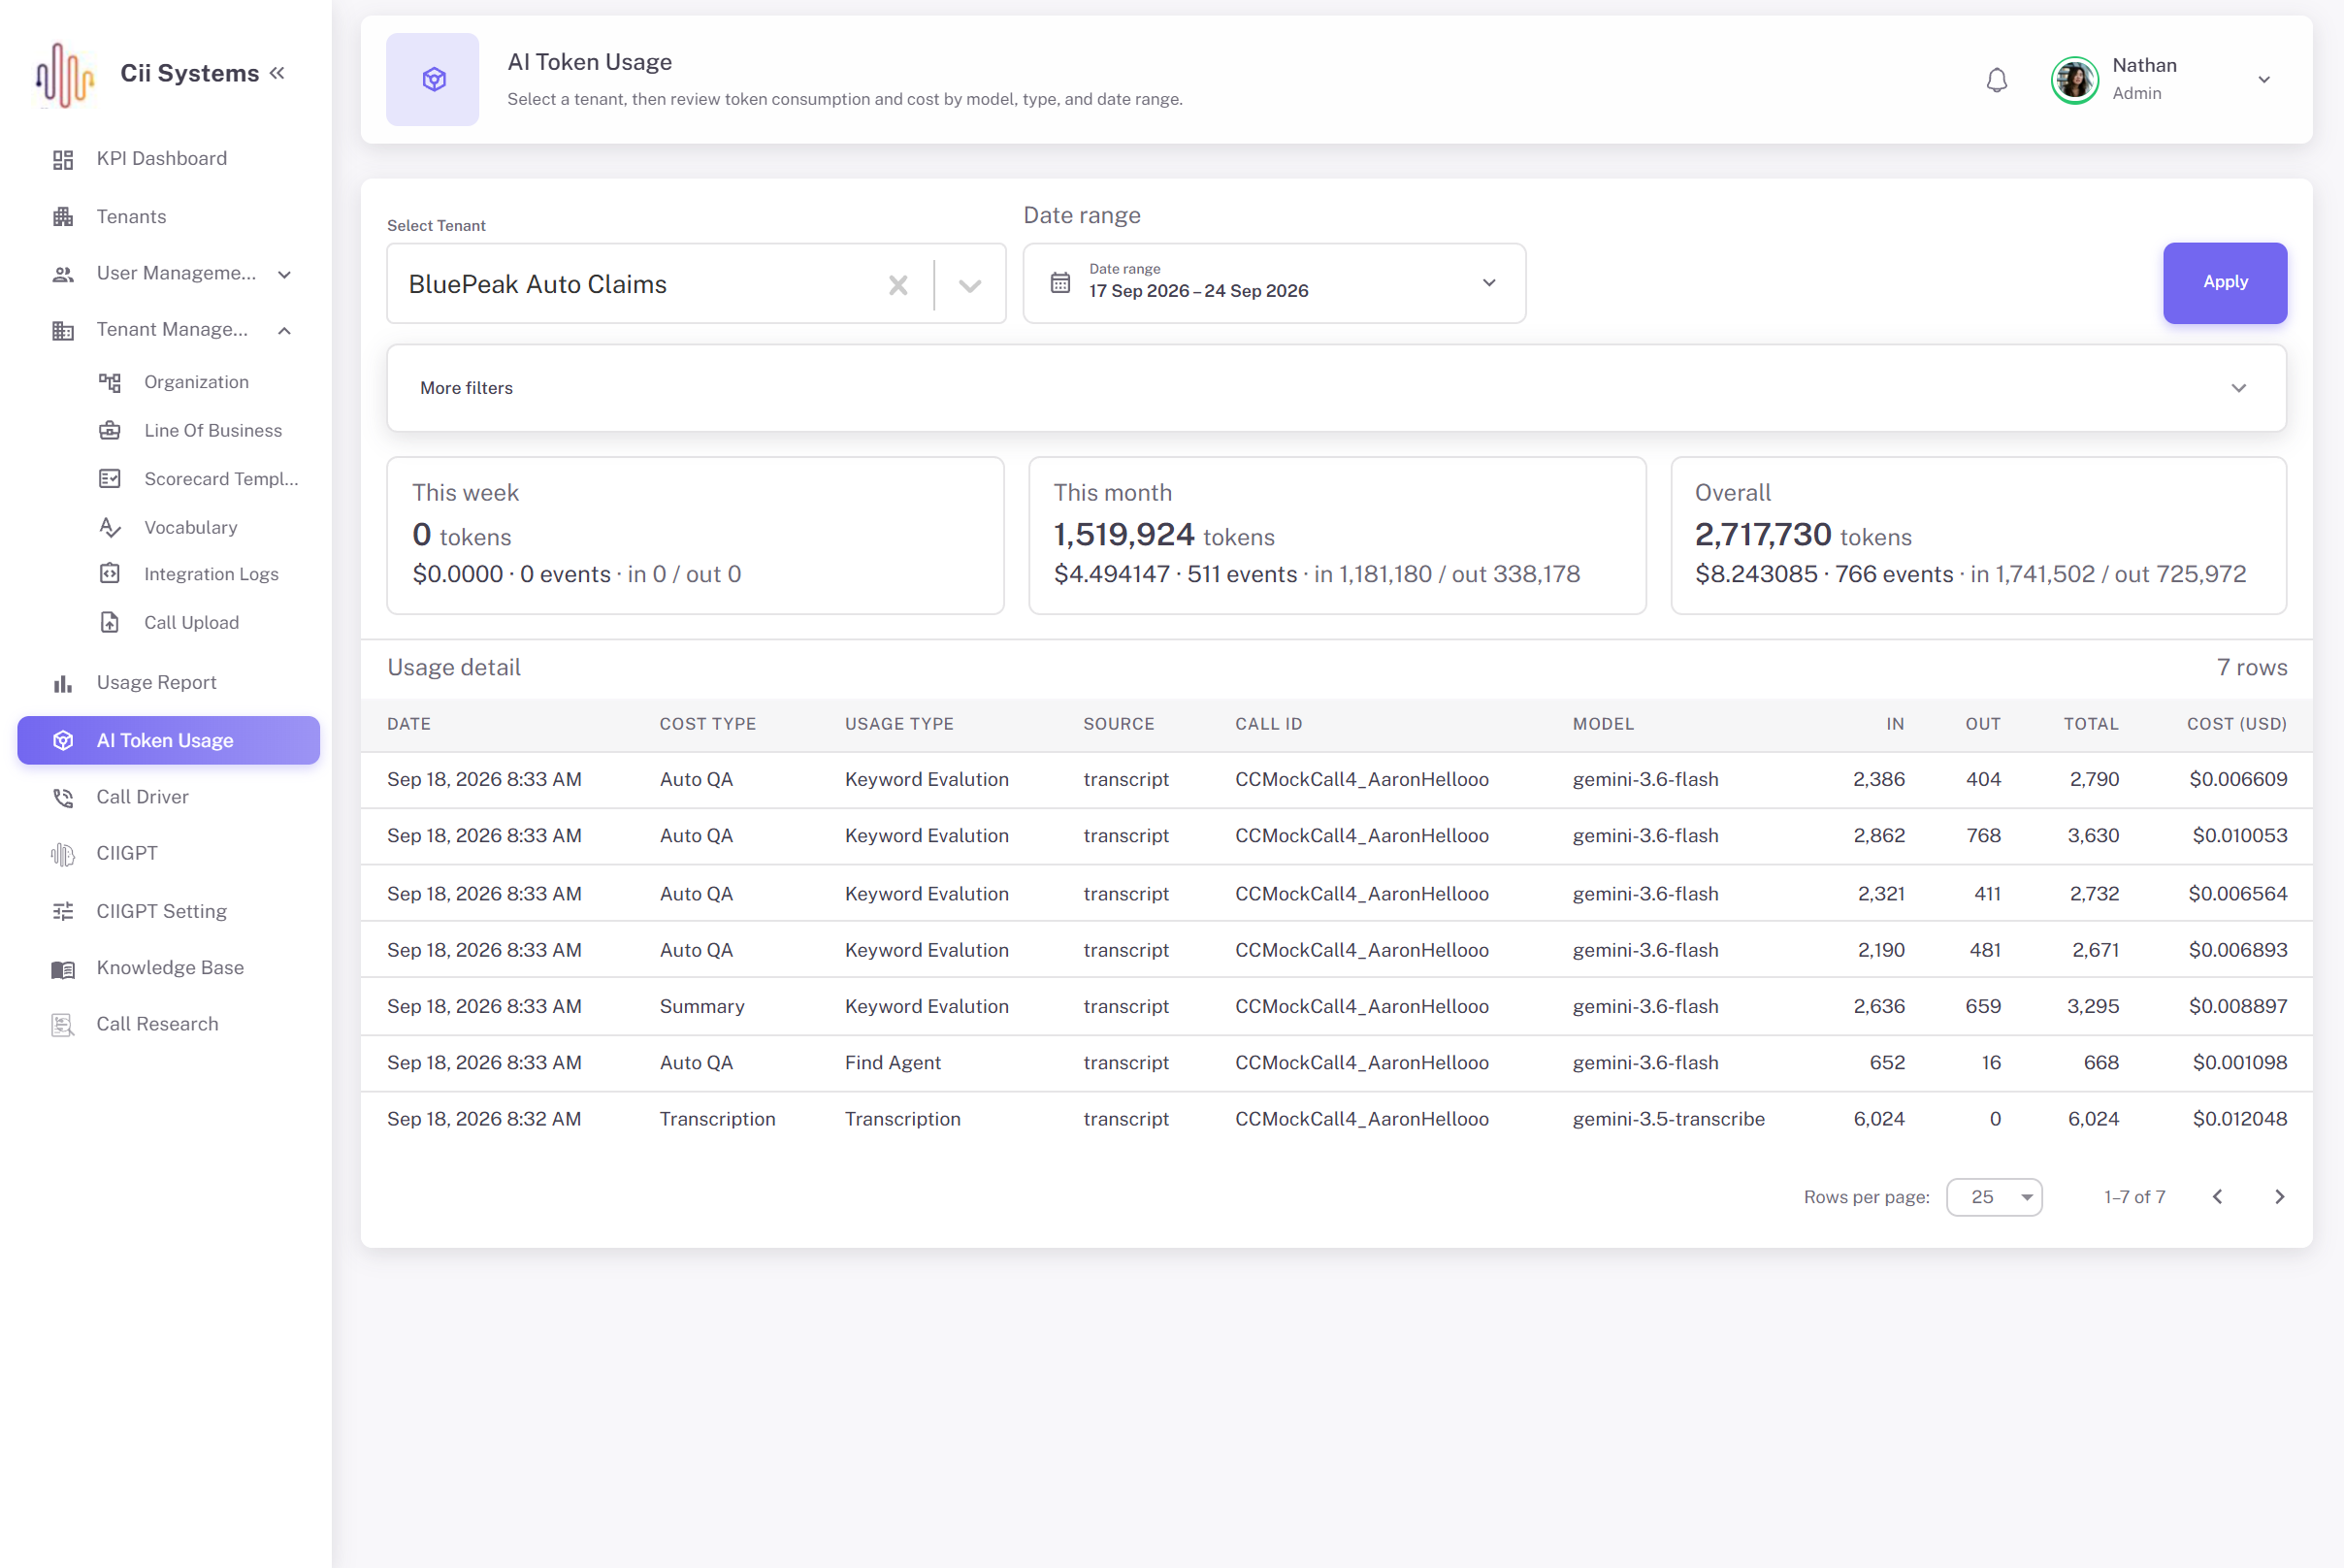
Gemini and Vertex AI evaluate configured prompts against call transcripts for behaviors that require conversational understanding.
Nested Scorecard Builder
Scorecards use Categories, Subcategories, and Definitions so detailed QA models remain manageable.
Keyword-Based Evaluation
Definitions can include keyword phrases, minimum match requirements, exact-match rules, and required-presence settings.
Context-Aware AI Prompts
The AI QA Chatbot can evaluate conversation behaviors where meaning matters more than exact wording.
Configurable AI & Keyword Weighting
Quality leaders decide how much each method contributes to a scoring Definition, with both weights totaling 100%.
One QA Standard
AI-assisted QA, automated scoring, manual reviewers, approvals, and rescoring all use the same scorecard structure.
Version-Controlled Scorecards
Updating scoring criteria creates a new version while preserving the rules behind previous evaluations.
Effective-Date Management
Scorecards can become active immediately, on a future date, or through a controlled historical process.
Hierarchy-Based Assignment
Scorecards can be assigned through the organization’s real hierarchy.
Excel Scorecard Import
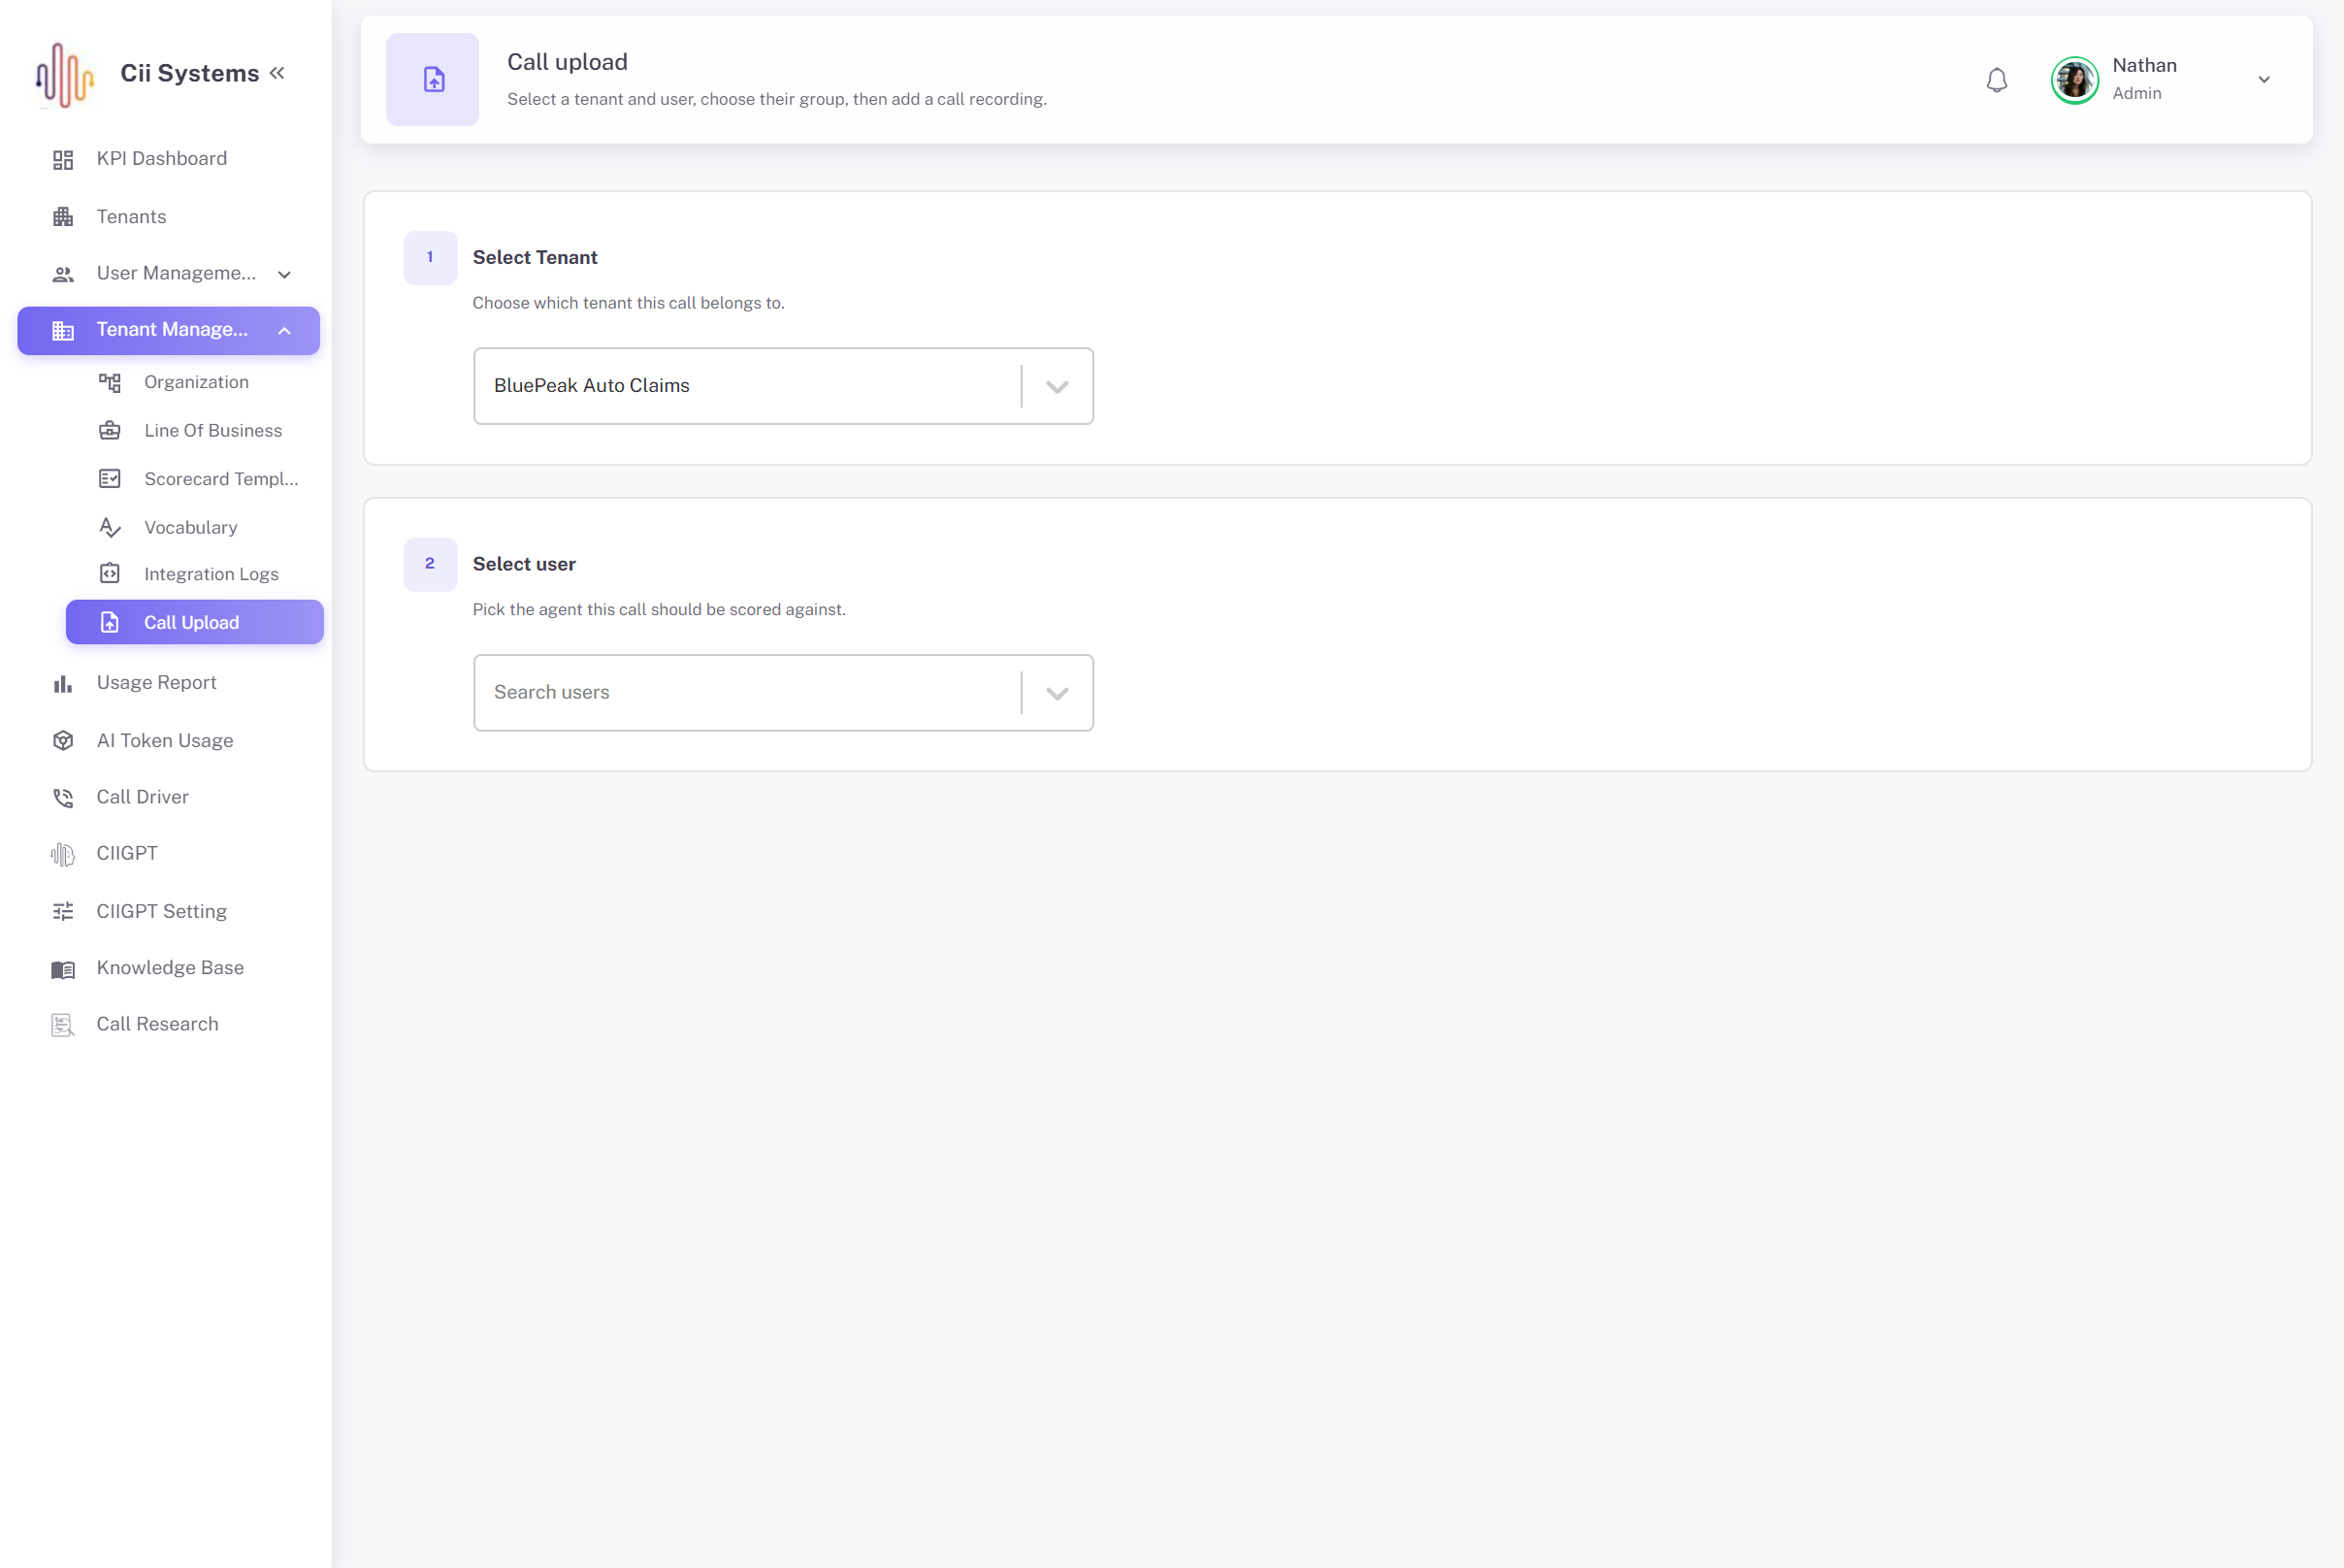
Existing scorecards can be uploaded through a controlled Amazon S3 workflow rather than manually recreated.
AI QA Chatbot, Call Evaluation & Scorecard Management
The AI QA Chatbot works inside the broader quality-assurance workflow rather than operating as a separate scoring system.
AI & Keyword Evaluation
- Each scoring Definition can combine keyword rules with AI prompts. Keywords identify clear evidence, while the AI QA Chatbot evaluates contextual behavior.
Contextual Conversation Analysis
- Gemini and Vertex AI can analyze areas such as empathy, active listening, professionalism, greeting quality, and objection handling.
Yes / No Evaluation
- Some AI prompts can return a straightforward Yes or No result when the quality requirement is binary.
Score-Based AI Evaluation
- Other behaviors can be scored within a configured minimum and maximum range.
Configurable Weighting
- Each Definition has separate Keyword and AI Prompt weights. Together, they total 100%, giving quality leaders control over how much AI influences a result.
Behavioral Scorecard Starters
- Quality teams can begin with behaviors such as Greeting, Verify Customer Information, Empathy & Active Listening, Professionalism, and Overcoming Objections.
Shared Human & AI Scoring
- Automated QA and manual reviewers see the same Categories, Subcategories, Definitions, evaluation questions, points, and scoring logic.
Version Control
- Scorecard changes create a new child version rather than overwriting the existing scoring rules.
Effective Dates & Historical Rescoring
- New templates can start immediately or from a selected date. Backdated changes can trigger controlled historical processing when required.
Review & Rescoring
- Approval, rejection, reopening, and rescoring remain connected to the original scorecard structure.
The main advantage is simple: the AI QA Chatbot and human reviewers follow the same quality rulebook.
Key Features
AI Call Center QA Chatbot
Context-aware AI analysis
Keyword matching
AI evaluation prompts
Keyword and AI weighting
Empathy and active-listening evaluation
Group and Department assignment
Scorecard version history
Historical rescoring
Human review workflow
AI-assisted automated QA
Configurable scorecard templates
Minimum keyword match counts
Yes / No AI evaluation
Automatic weight balancing
Professionalism evaluation
Location and Team assignment
Parent / child versions
Excel scorecard import
Approval and rejection
Gemini / Vertex AI evaluation
Categories and Subcategories
Exact-match controls
Score-based AI prompts
Greeting evaluation
Objection-handling analysis
Supervisor and Workgroup assignment
Effective dates
S3-based uploads
Reopening
Transcript-based call evaluation
Definition-level scoring
Required-keyword rules
Configurable score ranges
Customer verification checks
Organization-based scorecard assignment
Default scorecards
Historical migration
Manual QA queues
Historical scoring traceability
Architecture & Scalability
The administrative workspace uses React and TypeScript, with Material UI for interface components and Redux Toolkit for state management.
AWS AppSync exposes the GraphQL API, while AWS Lambda handles backend processing.
Authentication is managed through Amazon Cognito.
DynamoDB stores scorecard and scoring information. PostgreSQL is used for QA lists and related metrics.
Excel imports are stored through time-limited signed Amazon S3 uploads, which avoids treating a large import as a simple browser form submission.
Historical changes are handled asynchronously. When an effective date in the past requires older calls to move onto a different scorecard, Amazon SQS queues that migration instead of tying the work to the user's request.
Gemini / Vertex AI executes the AI prompts stored against scoring Definitions during automated QA.
The architecture separates user-facing configuration, scoring data, AI evaluation, import processing, and historical migration where it makes sense, while keeping them connected through the same QA workflow.
User Roles
- Quality Leader / Administrator: Creates scorecards, manages Categories and Definitions, configures AI QA Chatbot prompts and keyword rules, sets weighting, assigns organizational scope, manages versions, and controls effective dates.
- AI QA Chatbot / Automated QA: Evaluates transcribed calls using configured keywords, AI prompts, points, and scoring weights.
- Manual QA Scorer: Reviews customer conversations using the same scoring structure applied by automated QA.
- Reviewer: Manages review, approval, rejection, reopening, and rescoring within the original scoring framework.
- Operations / Management: Uses standardized QA results to understand quality across responsible teams, locations, and business units.
Results & Business Impact
The main benefit is not simply automating part of call review.
It is bringing the AI QA Chatbot and human reviewers onto the same scoring standard.
Key benefits include:
- One QA framework for AI and human evaluation
- More consistent interpretation of quality rules
- AI-assisted analysis of contextual agent behaviors
- Different scorecards for different teams
- Clear separation between keyword evidence and AI judgment
- Visible control over AI contribution to scoring
- Less dependence on developers for routine scorecard changes
- Historical versions that preserve previous scoring rules
- Better traceability when older evaluations are reviewed
- Controlled handling of effective dates
- Historical rescoring support
- Faster migration of existing scorecards through Excel import
- Consistent review, approval, reopening, and rescoring
- Better alignment between automated QA and manual quality teams
A quality leader can define a scoring standard, assign it through the organization, and update it later without losing the history behind earlier evaluations.
Use Cases
The AI QA Chatbot and scorecard platform can support:
- BPO companies
- Customer-service contact centers
- Enterprise call centers
- Inbound sales teams
- Outbound sales operations
- Collections departments
- Financial-services call centers
- Healthcare contact centers
- Telecom support teams
- Multi-location contact centers
- Enterprises with dedicated QA teams
- Businesses using call transcription
- Organizations introducing automated QA
- Companies combining AI evaluation with human review
Frequently Asked Questions
Talk To Us
About Your Project